type "llm integration services" into google and most vendor pages answer as if it's one thing: connect your product to an api, done. it isn't. a founder who buys "integration" expecting a chatbot wired to gpt-4 and actually needs a system grounded in their own documents ends up back at square one, paying twice.
the confusion is real enough that it shows up in the searches themselves, "what are llm integrations," "who are llm providers," people are asking definitional questions, not just shopping for a vendor. and building this in-house takes real time either way: roughly 18 to 24 months on your own engineering team's timeline, versus closer to 6 months through a team that's done it before.
picking the wrong point on that spectrum, not the hourly rate, is the expensive mistake.
the fix: llm integration is actually six distinct services wearing one name. here's what each one covers, which one a real product usually needs, and the honest tradeoffs of building it yourself versus bringing in a partner.
What you'll learn:
- which of six real service types "llm integration" actually refers to, and which one your product needs
- why building this in-house typically takes 18-24 months versus roughly 6 through an experienced partner, and where that time actually goes
- the real, independently-measured productivity data behind why companies are doing this at all
- what separates buying raw api access from buying a full-service partnership, and which one you're actually being quoted
- a practical checklist for vetting any vendor's claim before signing
what are llm integration services, actually?
"llm integration" is an umbrella term for six genuinely different services, and most vendor pages sell all six under one label without saying which one they mean:
the 6-part spectrum
raw api integration
wiring your product directly to openai, anthropic, or an open-source model. fastest to ship, but you own auth, logging, rate limits, and fallback logic yourself.
fine-tuning / customization
training a pretrained model further on your own data, a full fine-tune or a lighter method like lora. changes the model itself, not just what it's given at query time.
rag (retrieval-augmented generation)
pairing an llm with your own knowledge base so answers stay grounded in real documents, instead of retraining the model every time something changes. the technique traces back to a 2020 Meta AI research paper, not a marketing term invented by a vendor.
llm-as-a-service (llmaas)
cloud-hosted, pay-as-you-go access to a model, no infrastructure of your own to manage.
ai agents / automation
an llm powering a multi-step workflow, deciding what tool to use next, not just answering one question at a time.
monitoring and governance
bias checks, hallucination tracking, and compliance management once the system is live, not a one-time launch task.
dreamlaunch
Source: Hexaview Technologies, 2026.
a raw api call is a phone line to the model. a full integration is the whole call center built around it, the routing, the scripts, the person who steps in when the caller asks something the script didn't anticipate. most products need somewhere between those two, not either extreme.
if what you actually need is a conversational interface for customers, that's the chatbot end of this spectrum, covered in custom chatbot development services for overwhelmed founders.
if it's multi-step reasoning across tools and systems, that's the agent end, covered in 9 real AI agent development companies. this article is about the layer underneath both.
the RAG entry deserves a second look, since it's the point on the spectrum most founders actually need without realizing it's a distinct category. the original retrieval-augmented generation paper, published by Meta AI researchers in 2020, framed the problem plainly: a language model's factual knowledge is frozen at training time, and retraining it every time a product's underlying facts change is slow and expensive.
RAG solves that by keeping the model as-is and giving it a live lookup step instead, closer to an open-book exam than a memorization test. a support bot that needs to answer questions about this week's pricing, not last year's, is a RAG problem before it's an agent problem or a fine-tuning problem.
build it yourself, or bring in a partner?
the honest answer depends on how much of the spectrum above you actually need, and how much runway you have to build the parts you don't have in-house yet.
building llm capability: timeline
| fully in-house, from scratch |
18–24 months
|
| with an experienced implementation partner |
~6 months
|
dreamlaunch
Source: Hexaview Technologies, 2026. The gap is compute budget, specialized engineering talent, and data infrastructure most teams don't have sitting around internally.
that gap shows up in Gartner's own research too: at least 30% of generative AI projects get abandoned after proof of concept, driven by poor data quality, inadequate risk controls, escalating costs, or unclear business value, per Gartner analyst Rita Sallam.
most of the real work in llm integration happens after the demo works, not before, and the abandonment stat is what happens when that second phase isn't budgeted for.
the raw-api-versus-full-service framing above is the practical version of this decision. with raw api access, you own authentication, data flow, monitoring, and evaluation yourself. with a full-service partner, they manage integration, testing, compliance, and ongoing optimization end to end. neither is automatically right, it depends how much of that second list your team can actually staff.
why companies are integrating llms at all, in real numbers
most of what gets cited on vendor pages is a vendor's own claim. one number worth trusting more than most: a National Bureau of Economic Research study of over 5,000 customer-support agents found a genuine AI assistant lifted average productivity by 14%, and by 34% for newer, less-experienced workers specifically.
that's not a vendor's pitch deck, it's an independent academic study measuring a real deployed system against a real control group.
two things about it matter for a founder deciding whether to bother: the effect was real and measurable, and it was largest for the people least experienced at the task, not the people already good at it. if your product's real bottleneck is inconsistent quality from your newest hires or least experienced users, that's exactly the shape of problem this kind of integration is best evidenced to help with.
for a deeper, hands-on look at the actual engineering behind numbers like these: Cloud Guru's LLM Engineering Full Course walks through building the RAG, agent, and production layers described above.
what actually drives the cost?
no cross-referenced, independently-verified dollar figure exists for "llm integration services" as a category, the honest reason most vendor pages dodge a straight number here too. cost depends entirely on where your project sits on the six-part spectrum above, not on a single hourly rate.
the one lever vendors do agree matters: model selection. Master of Code's own guide frames choosing between GPT-4, Claude, Llama, or a smaller open-source model as a distinct early-stage decision, not an afterthought.
an oversized model for a simple task is one of the most common and most avoidable cost drivers in this category. a model that's larger, slower, and more expensive than the task actually requires doesn't buy better answers, it buys a bigger bill for the same result.
that bill scales directly with usage, not just complexity, since most model providers charge per token processed. a mid-sized product with a thousand daily users having multi-turn conversations can burn through several million tokens a month once retries and longer context windows are counted in, the kind of cost that stays invisible right up until the first real invoice arrives.
choosing a smaller, cheaper model for a task that doesn't need frontier-level reasoning is the single easiest lever a team controls before the usage bill grows large enough to matter.
for a real, cross-referenced dollar breakdown, the closest adjacent number is what an AI agent (one specific point on this spectrum) costs to build, covered separately: real ranges from $10,000 for a simple rule-based agent up to $400,000+ for a full multi-agent orchestration system, cross-referenced across two independent dev-shop guides.
a checklist before you sign anything
across vendor content in this space, the same practical vetting points show up repeatedly enough to trust as a real pattern, not one agency's sales pitch:
- verify security and compliance certifications directly (SOC 2 Type 2, ISO 27001), don't take a claim of "enterprise-grade security" at face value
- prioritize domain expertise in your actual use case over a generic AI shop's broad capability list
- confirm the engagement explicitly covers post-launch monitoring and support, not just the initial build, since the ongoing governance layer is real, recurring work, not a one-time deliverable
- ask which point on the six-part spectrum above the quote is actually pricing, since "llm integration" alone doesn't specify that
Source: Hexaview Technologies, 2026.
what a real integration looks like end to end
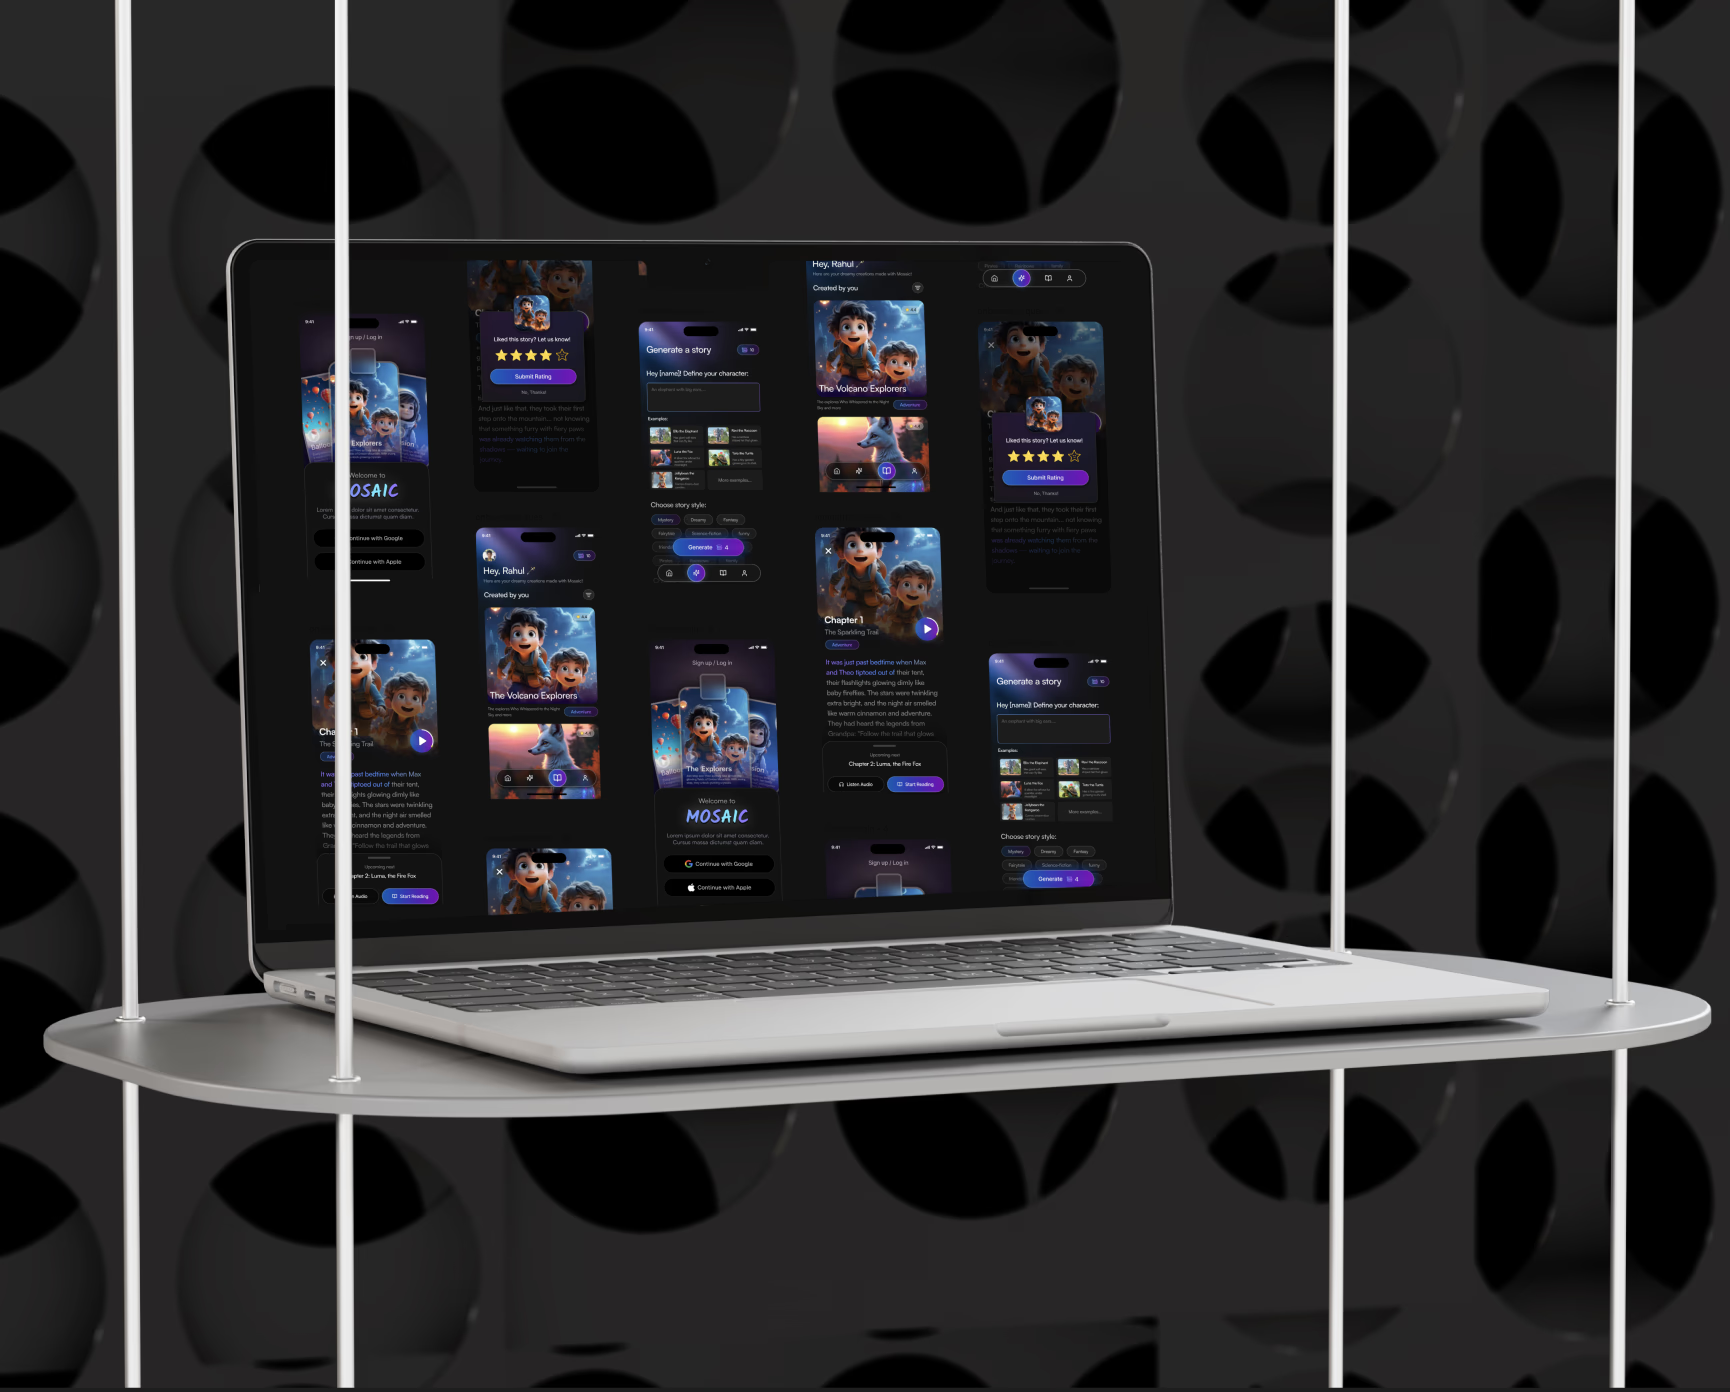
a real example that sits inside the spectrum above rather than at either extreme: Mosaic, an AI storytelling app for kids ages 3 to 12 that DreamLaunch designed and built end to end, live on both app stores in seven weeks.
the integration wasn't one model, it was three working together: OpenAI generating the story text from a child's one-line idea, DALL·E illustrating it, and text-to-speech narrating it.
all of it wrapped in a backend built around COPPA compliance and content-safety filtering from day one, not bolted on after launch. that's raw API integration (the model calls themselves), real product engineering around it (the app, the billing, the loading experience that keeps a 6-year-old from closing the app mid-generation), and governance (child-data protection, safety filtering), all three layers of the spectrum above, in one shipped product.
it's also the honest answer to "how long does this actually take": seven weeks for a real, live, three-model integration, not the 18-24 months the fully in-house timeline above describes, because the team doing it had already solved the infrastructure and integration problems on prior builds.
that's the practical case for the raw-api-versus-full-service framing above, restated concretely. the api calls to OpenAI and DALL·E are not, on their own, the hard part of a build like this.
the hard part is everything the checklist above is actually pointing at: the compliance layer that has to exist before a single child's data is stored, the loading-screen decision that determines whether a 6-year-old stays engaged long enough for the story to finish generating, the billing logic that has to work correctly the first time because there's no room for a broken payment flow in a product aimed at parents. that's the work "llm integration" is actually shorthand for, whichever point on the spectrum a given project lands on.